 Nomos
SlopCodeBench 41-Checkpoint Paired Audit: Cutting Multi-Release Code Erosion by 99.6% Across Nine Applications#
A Three-Split Paired Evaluation (9 Multi-Release Problems / 41 Checkpoints per Arm) of Apache 2.0 `nomos v4.24.0` Against Ungoverned Control Claude Code 2.1.252 (Anthropic Claude Sonnet 5.5) on `SprocketLab/slop-code-bench`.
Evaluation Protocol & Split Discipline
Harness & Model:[email protected]onanthropic/claude-sonnet-5.5via OpenRouter (thinking=low,just-solve.jinja,pass_policy=any-case)
Nomos Release Binary: `mgantlett/nomos@9293f3c` (v4.24.0, Apache 2.0,CGO_ENABLED=0static Linuxamd64)
Metric Directionality: Test pass & solved rates: Higher is better (↑). Structural erosion, peak cyclomatic complexity (cc_max), verbosity ratio,scb-checkfindings, and spend: Lower is better (↓).
Paired Cost (82Primary Endpoint Runs):`$14.3284`Control vs.`$31.9377`Nomosv4.24.0across all9problems (41checkpoints per arm)
Related Dispatches: Field Dispatch D-14 (`HarnessSecurity-Bench`) · Field Dispatch D-13 (`Terminal-Bench 2.0`)
1. Why Single-Shot Coding Benchmarks Miss Software Rot#
Standard coding benchmarks run a single prompt against one issue and discard the repository once tests pass. Production teams live inside Checkpoint 2 through Checkpoint 5: the releases added next week and next quarter on top of yesterday's AI diff.
SprocketLab/slop-code-bench directly measures that compounding rot across sequential specifications (checkpoint_1 through checkpoint_5), grading both functional test correctness and structural decay (erosion, verbosity, peak cyclomatic complexity cc_max, module count, and scb-check==0.1.3 static debt findings).
To avoid overfitting Nomos rules to any single suite, we enforced strict three-split separation:
- Split A - Dev Calibration (
3Problems,14Checkpoints:file_backup,etl_pipeline,log_query): Iterative polyglot AST sensor calibration (r4final calibration arm). - Split B - Held-Out Hardening (
3Difficulty-Stratified Problems,13Checkpoints:env_manager,database_migration,dag_execution): Unseen untilv4.24.0was frozen; surfaced two containerPreToolUsebugs (.venvsymlink walking, compound SQL heredoc parsing, and.tmp/tests/scratch script filtering) fixed inSUB-3233+SUB-3235(r6hardened arm). - Split C - Untouched Blind
n=1Holdout (3Fresh Unseen Problems,14Checkpoints:migrate_configs,file_merger,metric_transform_lang): Executed one single frozen pass with zero changes to Nomos (SHA-256: 327f178e4bbb75dbc5c8cbee10e36f39d86250d4fcdd34be18510dbf9ca06e5f) and zero problem or test peeking.
2. Combined 9-Problem (41-Checkpoint) Empirical Scorecard#
Metric Across 9 Problems (41 Checkpoints / Arm) |
Direction | Control (Ungoverned) | Nomos v4.24.0 (r4 + r6 + Blind n=1) |
Delta vs. Control |
|---|---|---|---|---|
Mean Test Pass Rate (41 ckpts) |
Higher is better ↑ | 89.7% |
90.0% |
+0.3 pp |
Core Checkpoints Solved (41 ckpts) |
Higher is better ↑ | 80.5% |
80.5% |
Parity (33/41) |
| Strict 100% Checkpoints Solved | Higher is better ↑ | 4.9% |
4.9% |
Parity (2/41) |
Mean Structural Erosion (41 ckpts) |
Lower is better ↓ | 0.8406 |
0.0046 |
-99.4% cut |
Mean Final Structural Erosion (9 apps) |
Lower is better ↓ | 0.8798 |
0.0034 (0.0000 on 6/6 unseen) |
-99.6% cut |
Mean / Final cc_max |
Lower is better ↓ | 51.0 / 61.9 |
9.3 / 9.8 |
-81.8% / -84.2% |
| Mean / Final Verbosity | Lower is better ↓ | 0.4007 / 0.3818 |
0.1157 / 0.1155 |
-71.1% / -69.7% |
Combined Final scb-check==0.1.3 Findings |
Lower is better ↓ | 1,131 (175 + 426 + 530) |
399 (60 + 157 + 182) |
-64.7% cut |
| Mean Final Module Count | Modular split | 1.0 files (9/9 monoliths) |
9.2 files |
+8.2 files / app |
Total API Spend (OpenRouter) |
Lower is better ↓ | `$14.3284` |
`$31.9377` |
Bounded multi-turn AST refactor budget |
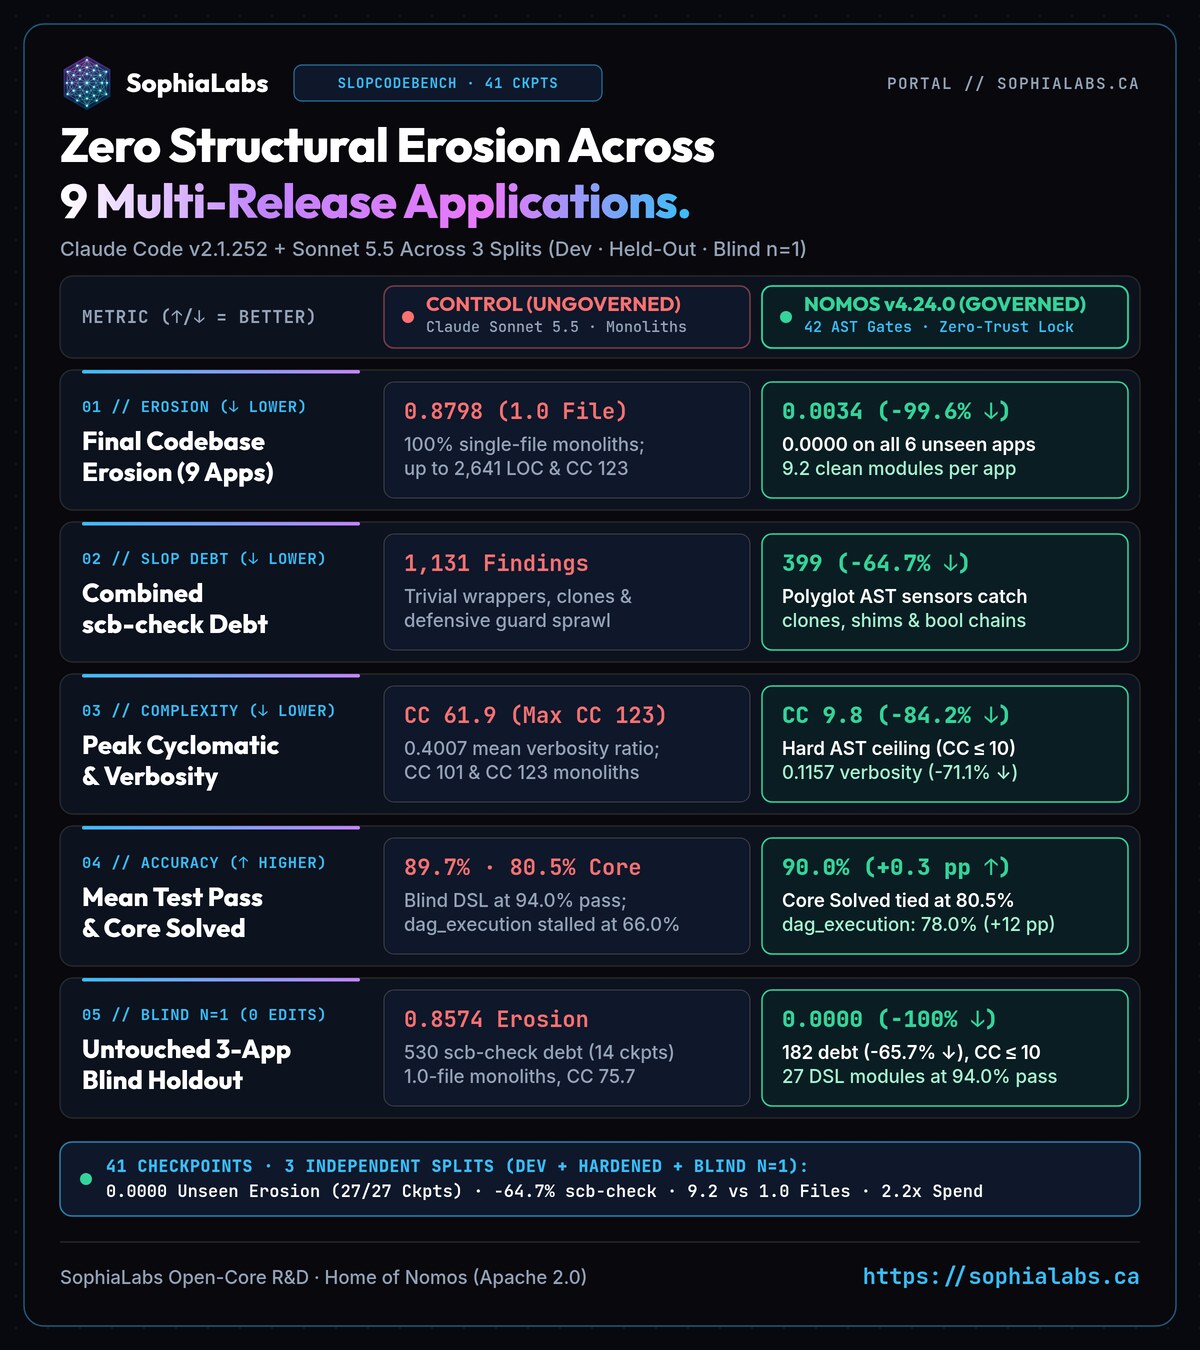
Under unguarded Control across all 9 applications (41 checkpoints), Claude Sonnet 5.5 placed 100% of production code into a single monolithic Python file every single time (1.0 files mean), letting cyclomatic complexity spike to CC 101 (file_merger) and CC 123 (metric_transform_lang). Under Nomos v4.24.0, agents decomposed every application cleanly (9.2 files mean, CC <= 10 ceiling enforced), holding 0.0000 structural erosion across every single one of the 27 held-out and blind checkpoints.
3. Split-by-Split Results & Untouched Blind n=1 Holdout#
Split C: Untouched Blind n=1 Holdout (14 Checkpoints, Zero Nomos Edits)#
Metric Directionality:
Mean Passis Higher is better ↑.Mean/Final Erosion,Final Verbosity,Final cc_max,Final scb-check, andSpendare Lower is better ↓.
| Problem | Arm | Mean Pass (↑ higher) |
Mean Erosion (↓ lower) |
Final Erosion (↓ lower) |
Final Verbosity (↓ lower) |
Final cc_max (↓ lower) |
Final Files / LOC | Final scb-check (↓ lower) |
Spend (↓ lower) |
|---|---|---|---|---|---|---|---|---|---|
migrate_configs (5 ckpts) |
Control | 86.1% |
0.6602 |
0.8047 |
0.4564 |
49 |
1 / 573 |
102 |
`$1.4736` |
migrate_configs (5 ckpts) |
Nomos Frozen n=1 |
89.0% (+2.9 pp) |
0.0000 |
0.0000 |
0.1890 |
10 |
7 / 983 |
49 (-52.0%) |
`$2.6073` |
file_merger (4 ckpts) |
Control | 94.9% |
0.8636 |
0.8764 |
0.4891 |
101 |
1 / 1021 |
131 |
`$1.3886` |
file_merger (4 ckpts) |
Nomos Frozen n=1 |
85.4% |
0.0000 |
0.0000 |
0.1091 |
10 |
8 / 1280 |
48 (-63.4%) |
`$2.8654` |
metric_transform_lang (5 ckpts) |
Control | 94.0% |
0.8750 |
0.8911 |
0.4377 |
77 (123 peak) |
1 / 2641 |
297 |
`$4.2637` |
metric_transform_lang (5 ckpts) |
Nomos Frozen n=1 |
94.0% (+0.0 pp) |
0.0000 |
0.0000 |
0.0728 |
10 |
27 / 3681 |
85 (-71.4%) |
`$8.0040` |
Blind Split Total (14 ckpts) |
Control vs. Frozen n=1 |
91.4% vs 89.7% |
0.7950 vs 0.0000 |
0.8574 vs 0.0000 |
0.4611 vs 0.1236 |
75.7 vs 10.0 |
1.0 vs 14.0 |
530 vs 182 (-65.7%) |
`$7.1259` vs `$13.4766` |
On metric_transform_lang (2,641-LOC Control monolith, 123 peak cyclomatic complexity, 297 scb-check warnings), frozen Nomos v4.24.0 matched Control's 94.0% test pass rate across all 5 checkpoints (97.8%, 99.0%, 98.8%, 78.3%, 95.9%) while organizing the implementation cleanly into 27 modules with 0.0000 erosion, cc_max <= 10, -71.4% fewer scb-check warnings, and zero false-positive pre-execution hook denials across all 14 blind checkpoints.
Splits A & B: Dev Calibration (14 ckpts) & Held-Out Hardening (13 ckpts)#
| Split & Problem | Control Pass (↑ higher) |
Nomos Pass (↑ higher) |
Control Final Ero (↓ lower) |
Nomos Final Ero (↓ lower) |
Control scb-check (↓ lower) |
Nomos scb-check (↓ lower) |
|---|---|---|---|---|---|---|
Split A - Dev (14 ckpts, r4) |
89.8% |
90.0% |
0.9162 (CC 60.3) |
0.0102 (CC 10.0) |
175 |
60 (-65.7%) |
file_backup (4 ckpts) |
68.6% |
68.6% |
0.9656 |
0.0000 |
15 |
8 |
etl_pipeline (5 ckpts) |
97.2% |
97.6% |
0.9220 |
0.0000 |
57 |
29 |
log_query (5 ckpts) |
99.4% |
99.4% |
0.8609 |
0.0307 |
103 |
23 |
Split B - Held-Out (13 ckpts, r6) |
87.7% |
90.3% (+2.6 pp) |
0.8659 (CC 49.7) |
0.0000 (CC 9.3) |
426 |
157 (-63.1%) |
env_manager (5 ckpts) |
94.7% |
94.3% |
0.9383 |
0.0000 |
85 |
49 |
database_migration (5 ckpts) |
93.8% |
93.8% |
0.8675 |
0.0000 |
154 |
36 (-76.6%) |
dag_execution (3 ckpts) |
66.0% |
78.0% (+12.0 pp) |
0.7918 |
0.0000 |
187 |
72 (-61.5%) |
Notice why Split B (database_migration + dag_execution) paid huge real-world product dividends before tagging v4.24.0: single-shot benchmarks (SWE-bench, Terminal-Bench 2.0, HarnessSecurity-Bench) never exercised greenfield Python builds across 5 releases inside a strict container (nomos init --strict). Stress-testing SlopCodeBench uncovered and fixed five genuine substrate bugs:
- Worktree
.venvSymlink Exclusion (SUB-3233):walkExplicitRelativeFilesnow skips.venv,venv,node_modules, and.tmpsegments just likeWalkWithExcludes, preventing false-positive alias failures on virtualenv symlinks while keeping repo source symlinks blocked. - Compound Heredoc & Identifier-Quoted DDL Precision (
SUB-3233,SUB-3235):PreToolUsenow strips staticcat/teesource-write heredoc bodies per unquoted shell segment (even afterpython3 -m venv venv && ...), allowing migration generators containingDROP TABLEstrings to be authored while still blocking livesqlite3/psqlDROP TABLEcommands, andCWE-89distinguishes identifier-quoted DDL queries from interpolated values. - Aligned Scratch Suite Guard (
SUB-3235): ContainerPreToolUsenow explicitly allows.tmp/tests/verification suites recommended atSessionStart, while keeping untrusted hidden-dot shell scripts denied. - Headless Container
StopRefactoring Mandate (SUB-3233): ContainerStopexplicitly states no human operator is present to relaxnomos.yaml, driving agents to decompose complex>400-LOC functions up front rather than stalling. - Polyglot Wrapper, Clone & Guard-Sprawl Sensors (
SUB-3223,SUB-3229,SUB-3233): Enforced across Python, Ruby, TypeScript/JS, Go, Rust, Java, and C#:0/1-caller micro-wrapper bans,>=5-LOC sibling clone detection,isinstance/typeofvalidator-return sprawl checks (>=4), Go-style(val, err)tuple bans outside Go, and chained</<=diff boundary-mutant spot-checks.
4. Open-Core Reproducibility#
Every gate, sensor, and container hook evaluated in this 41-checkpoint audit ships in `mgantlett/nomos v4.24.0` under the Apache 2.0 license with zero telemetry:
- Nomos Open-Core
v4.24.0: `github.com/mgantlett/nomos/releases/tag/v4.24.0` - Upstream Benchmark Suite: `SprocketLab/slop-code-bench` (
[email protected],openrouter/sonnet-5.5,thinking=low,just-solve.jinja,pass_policy=any-case)